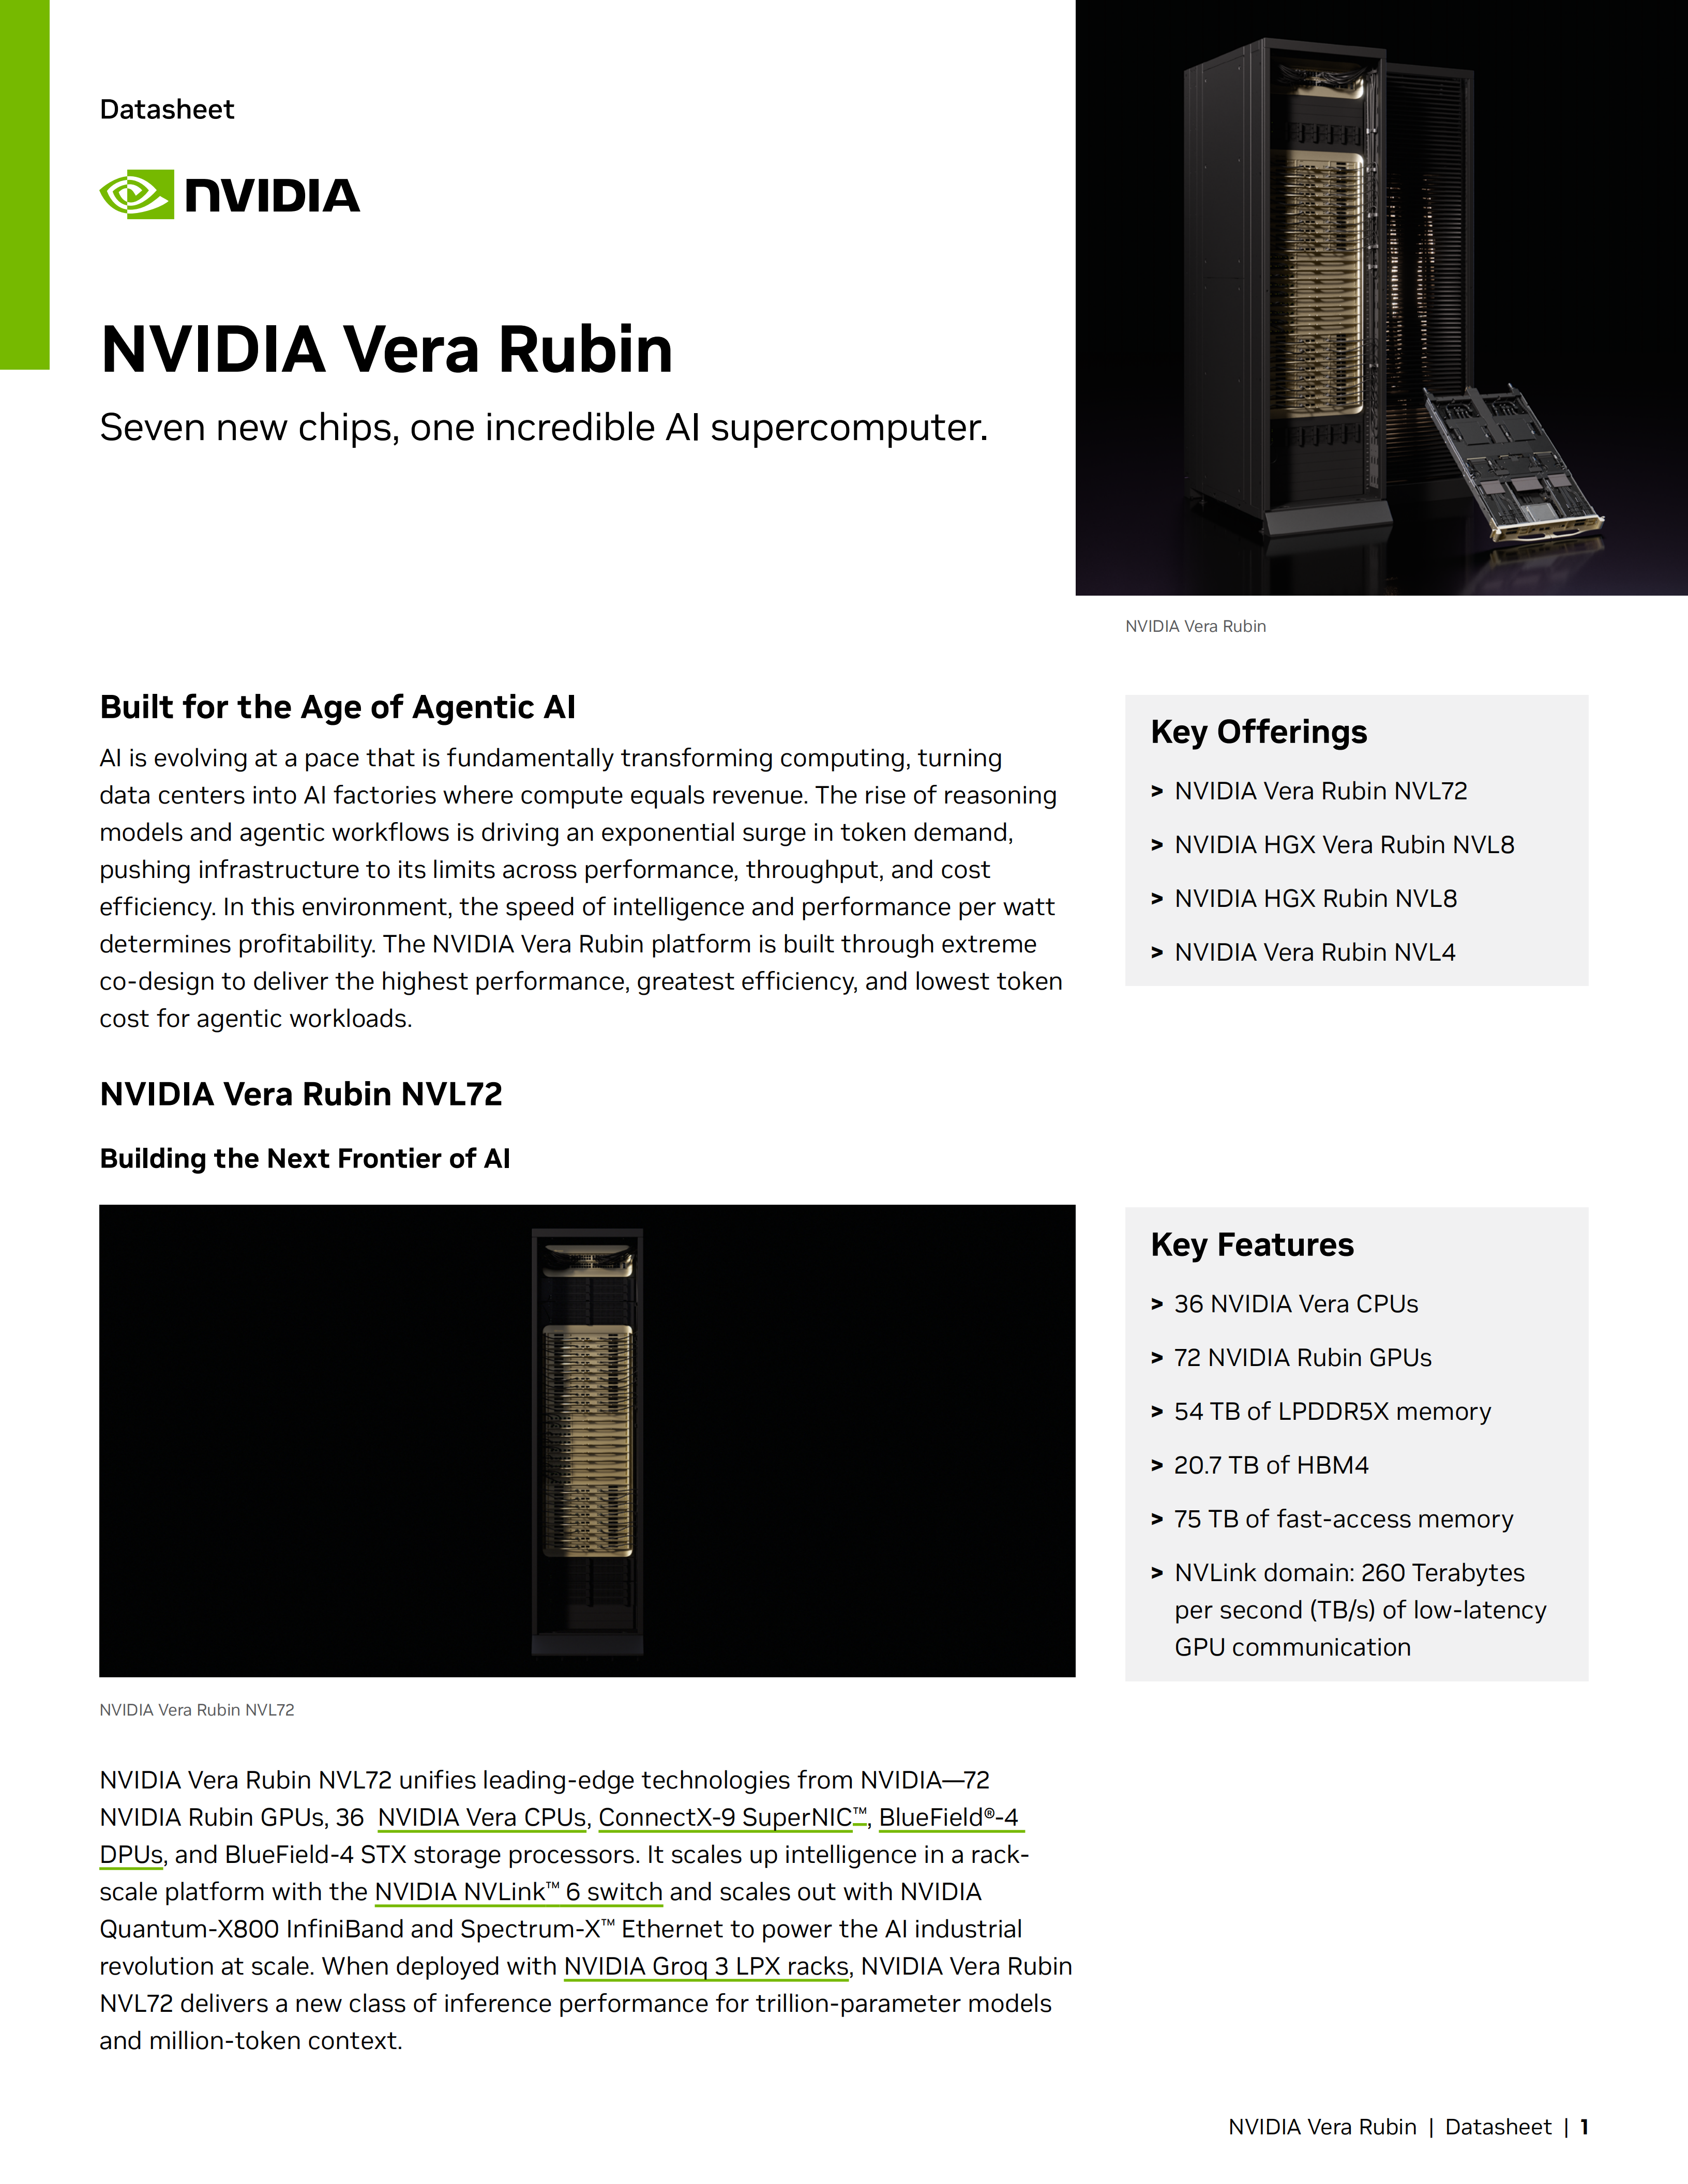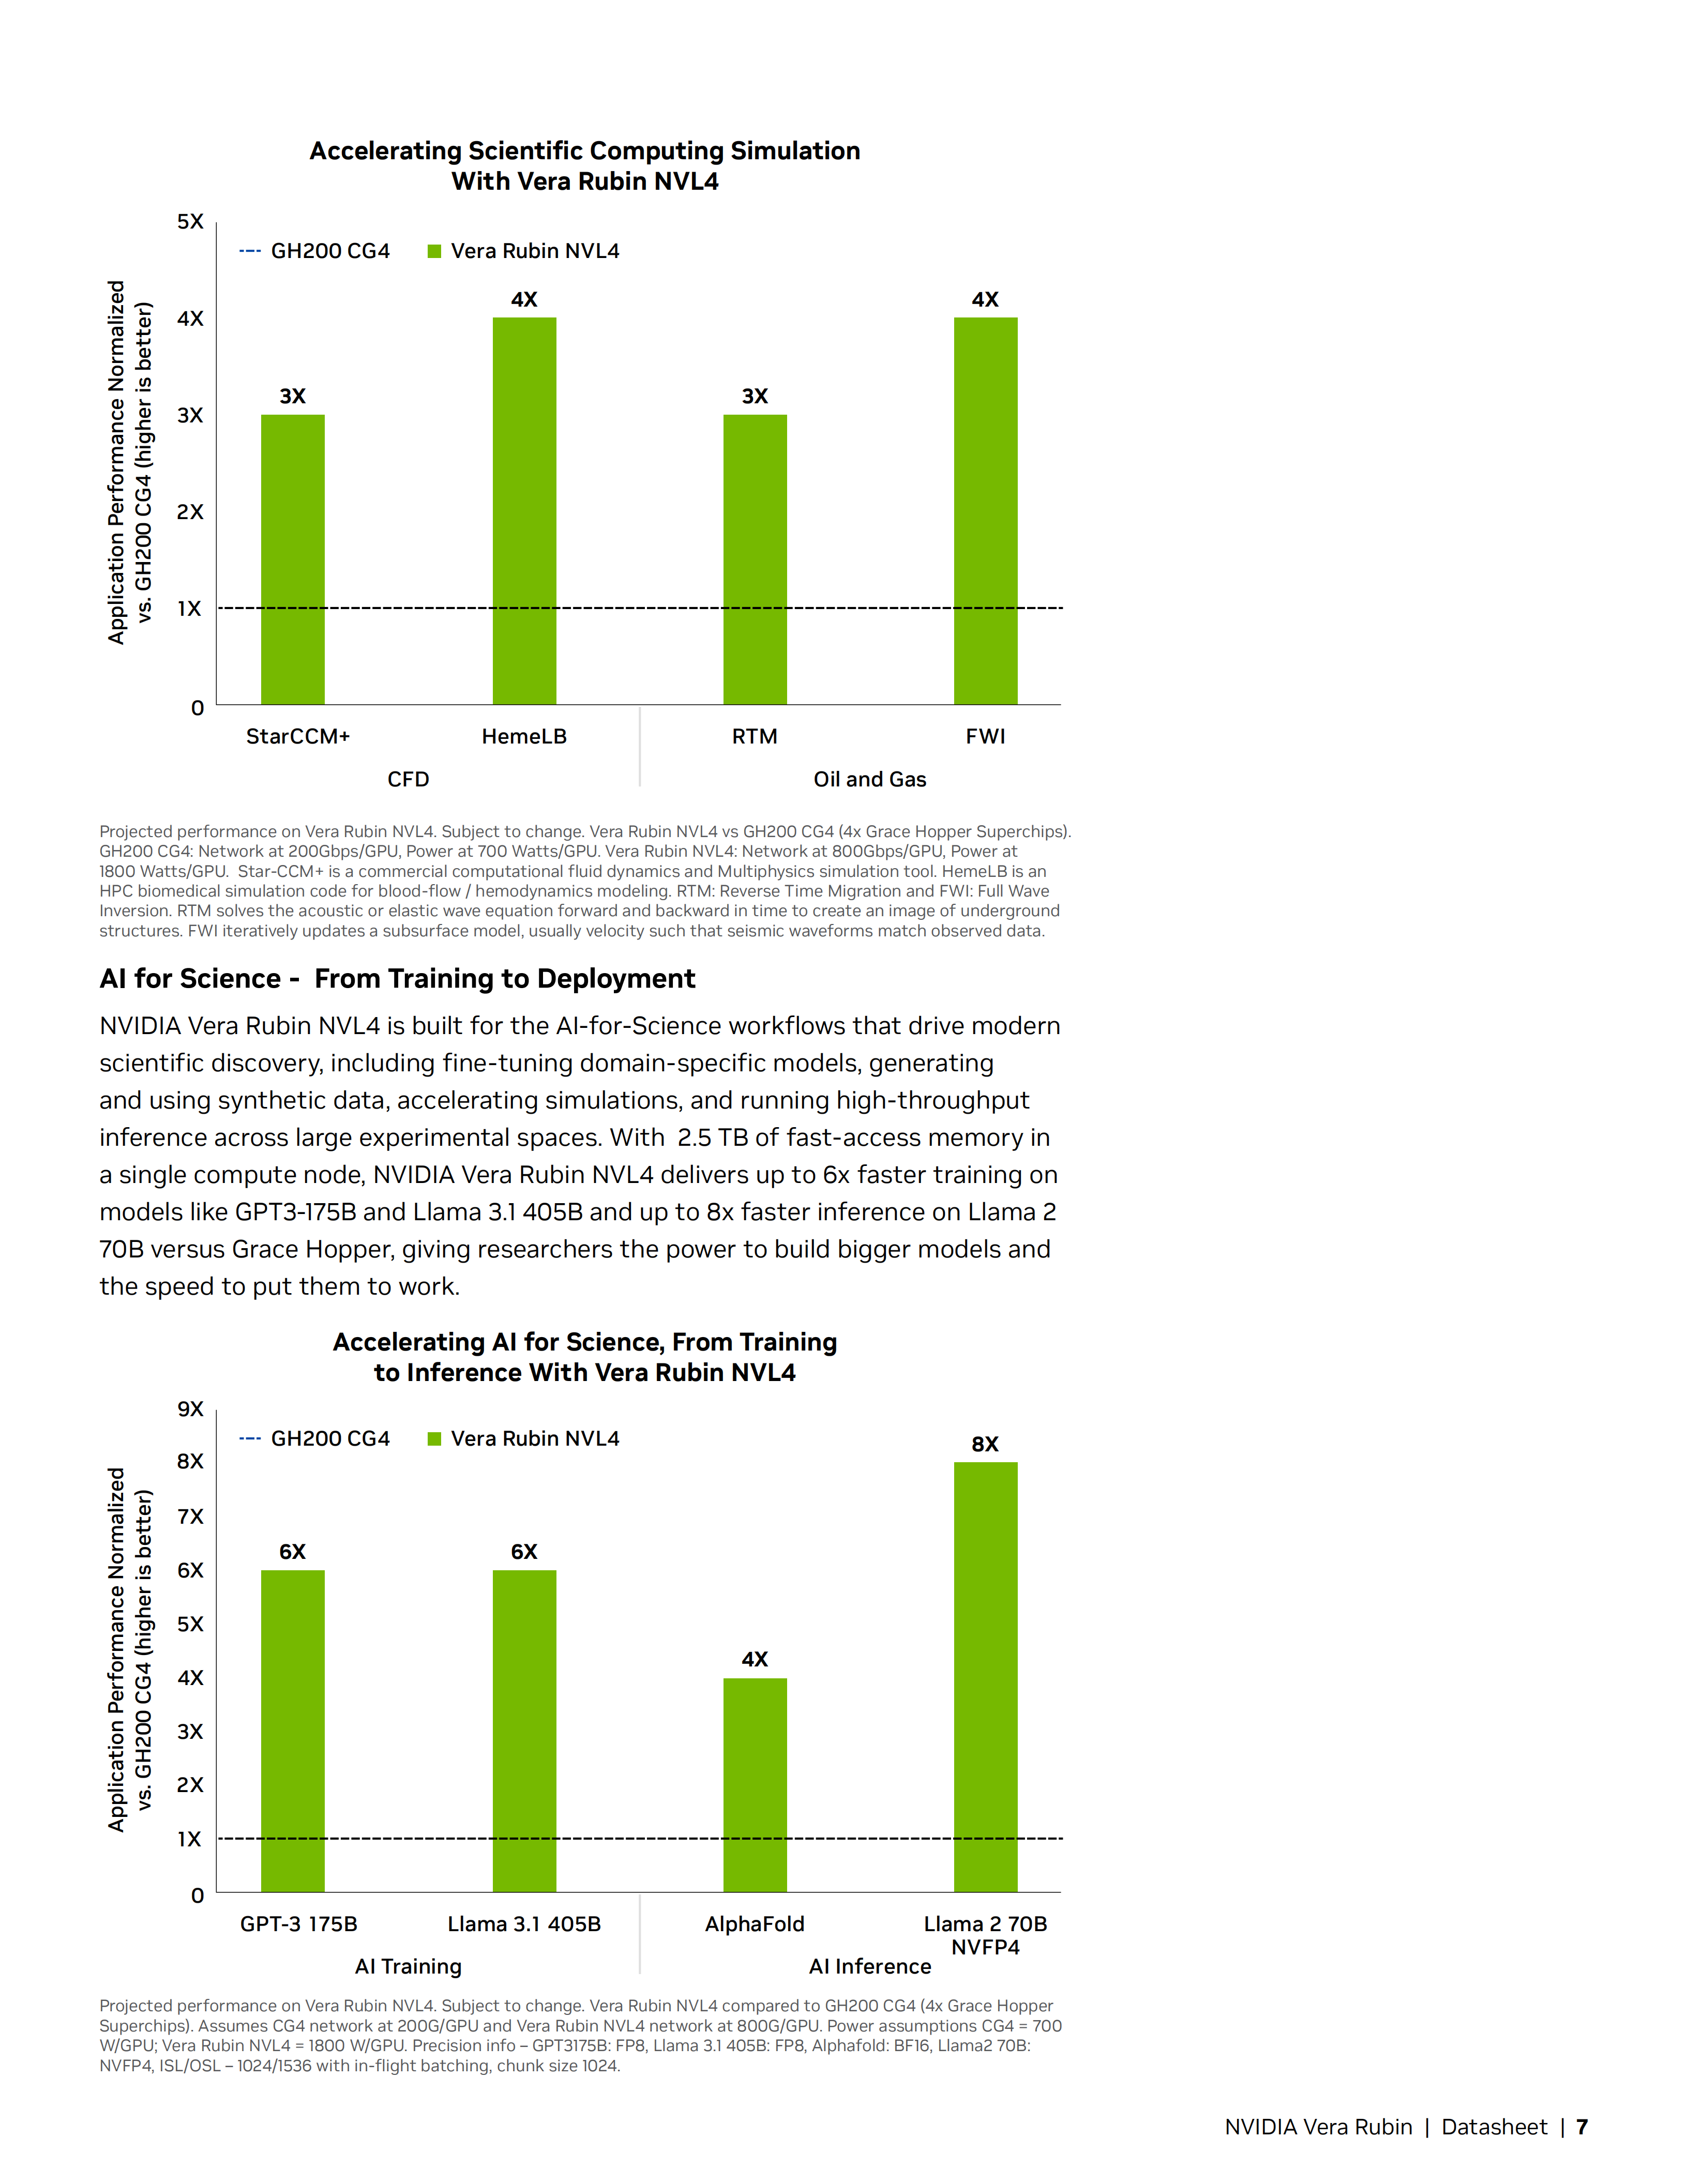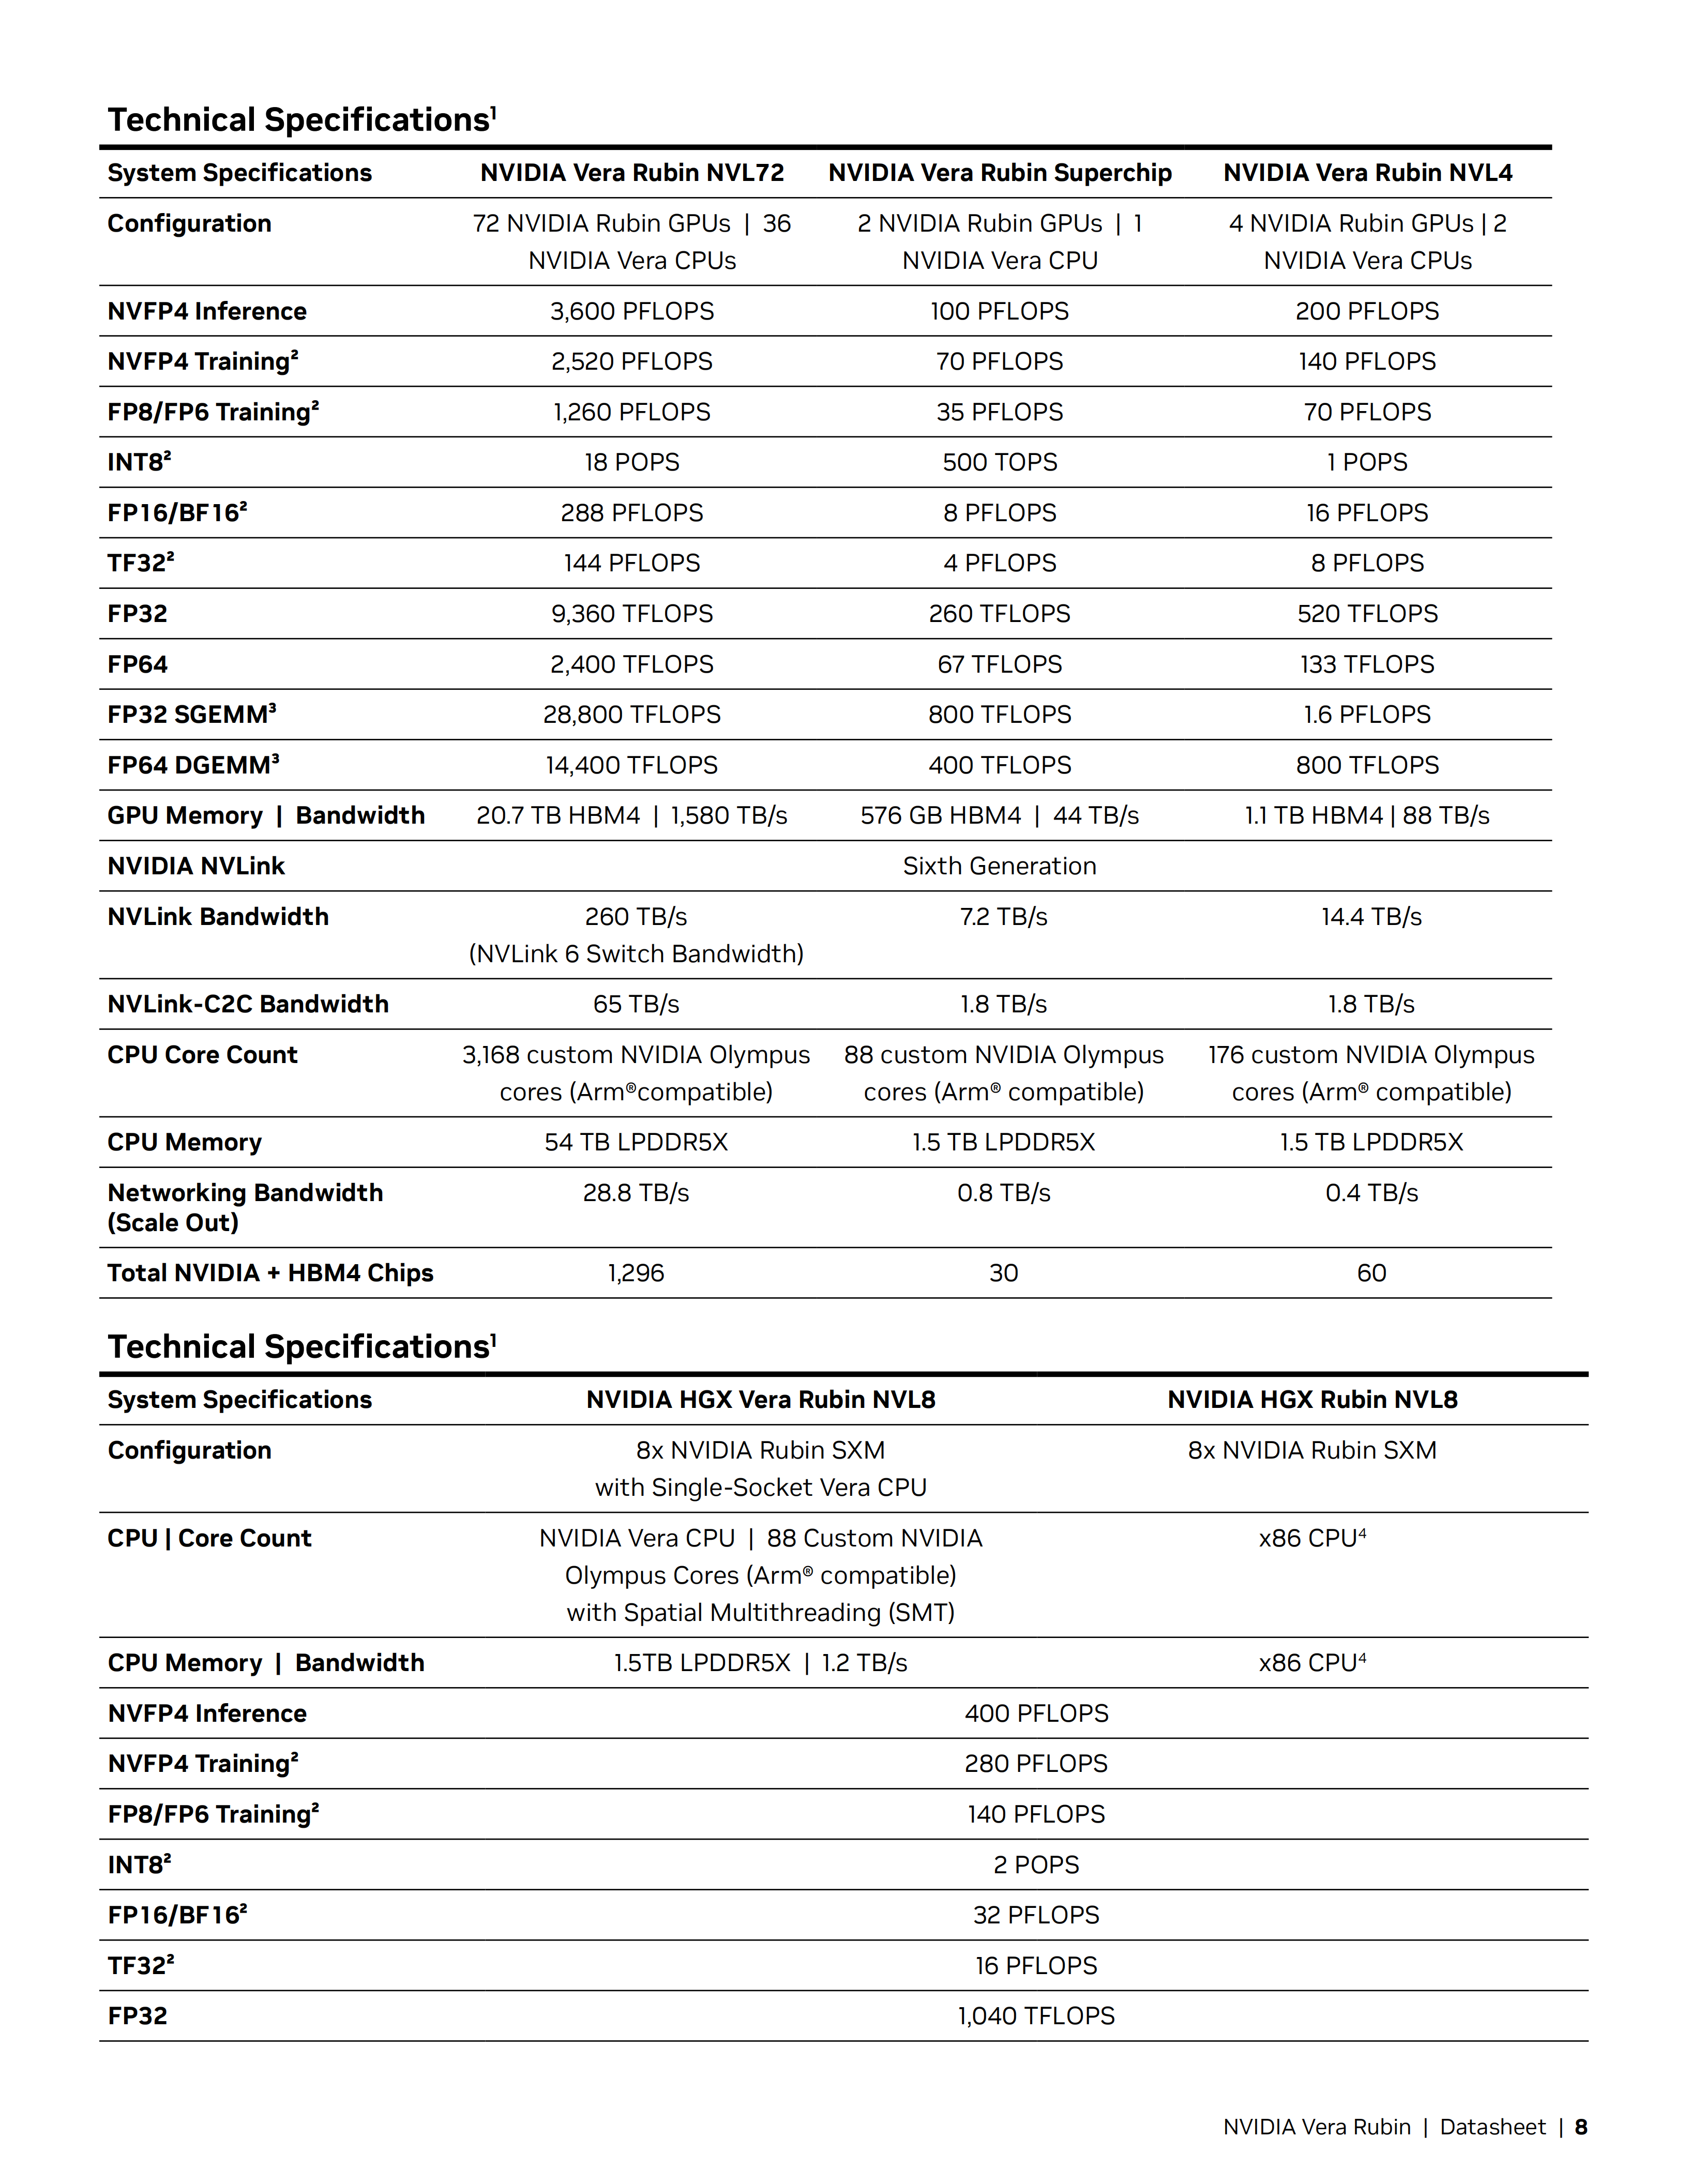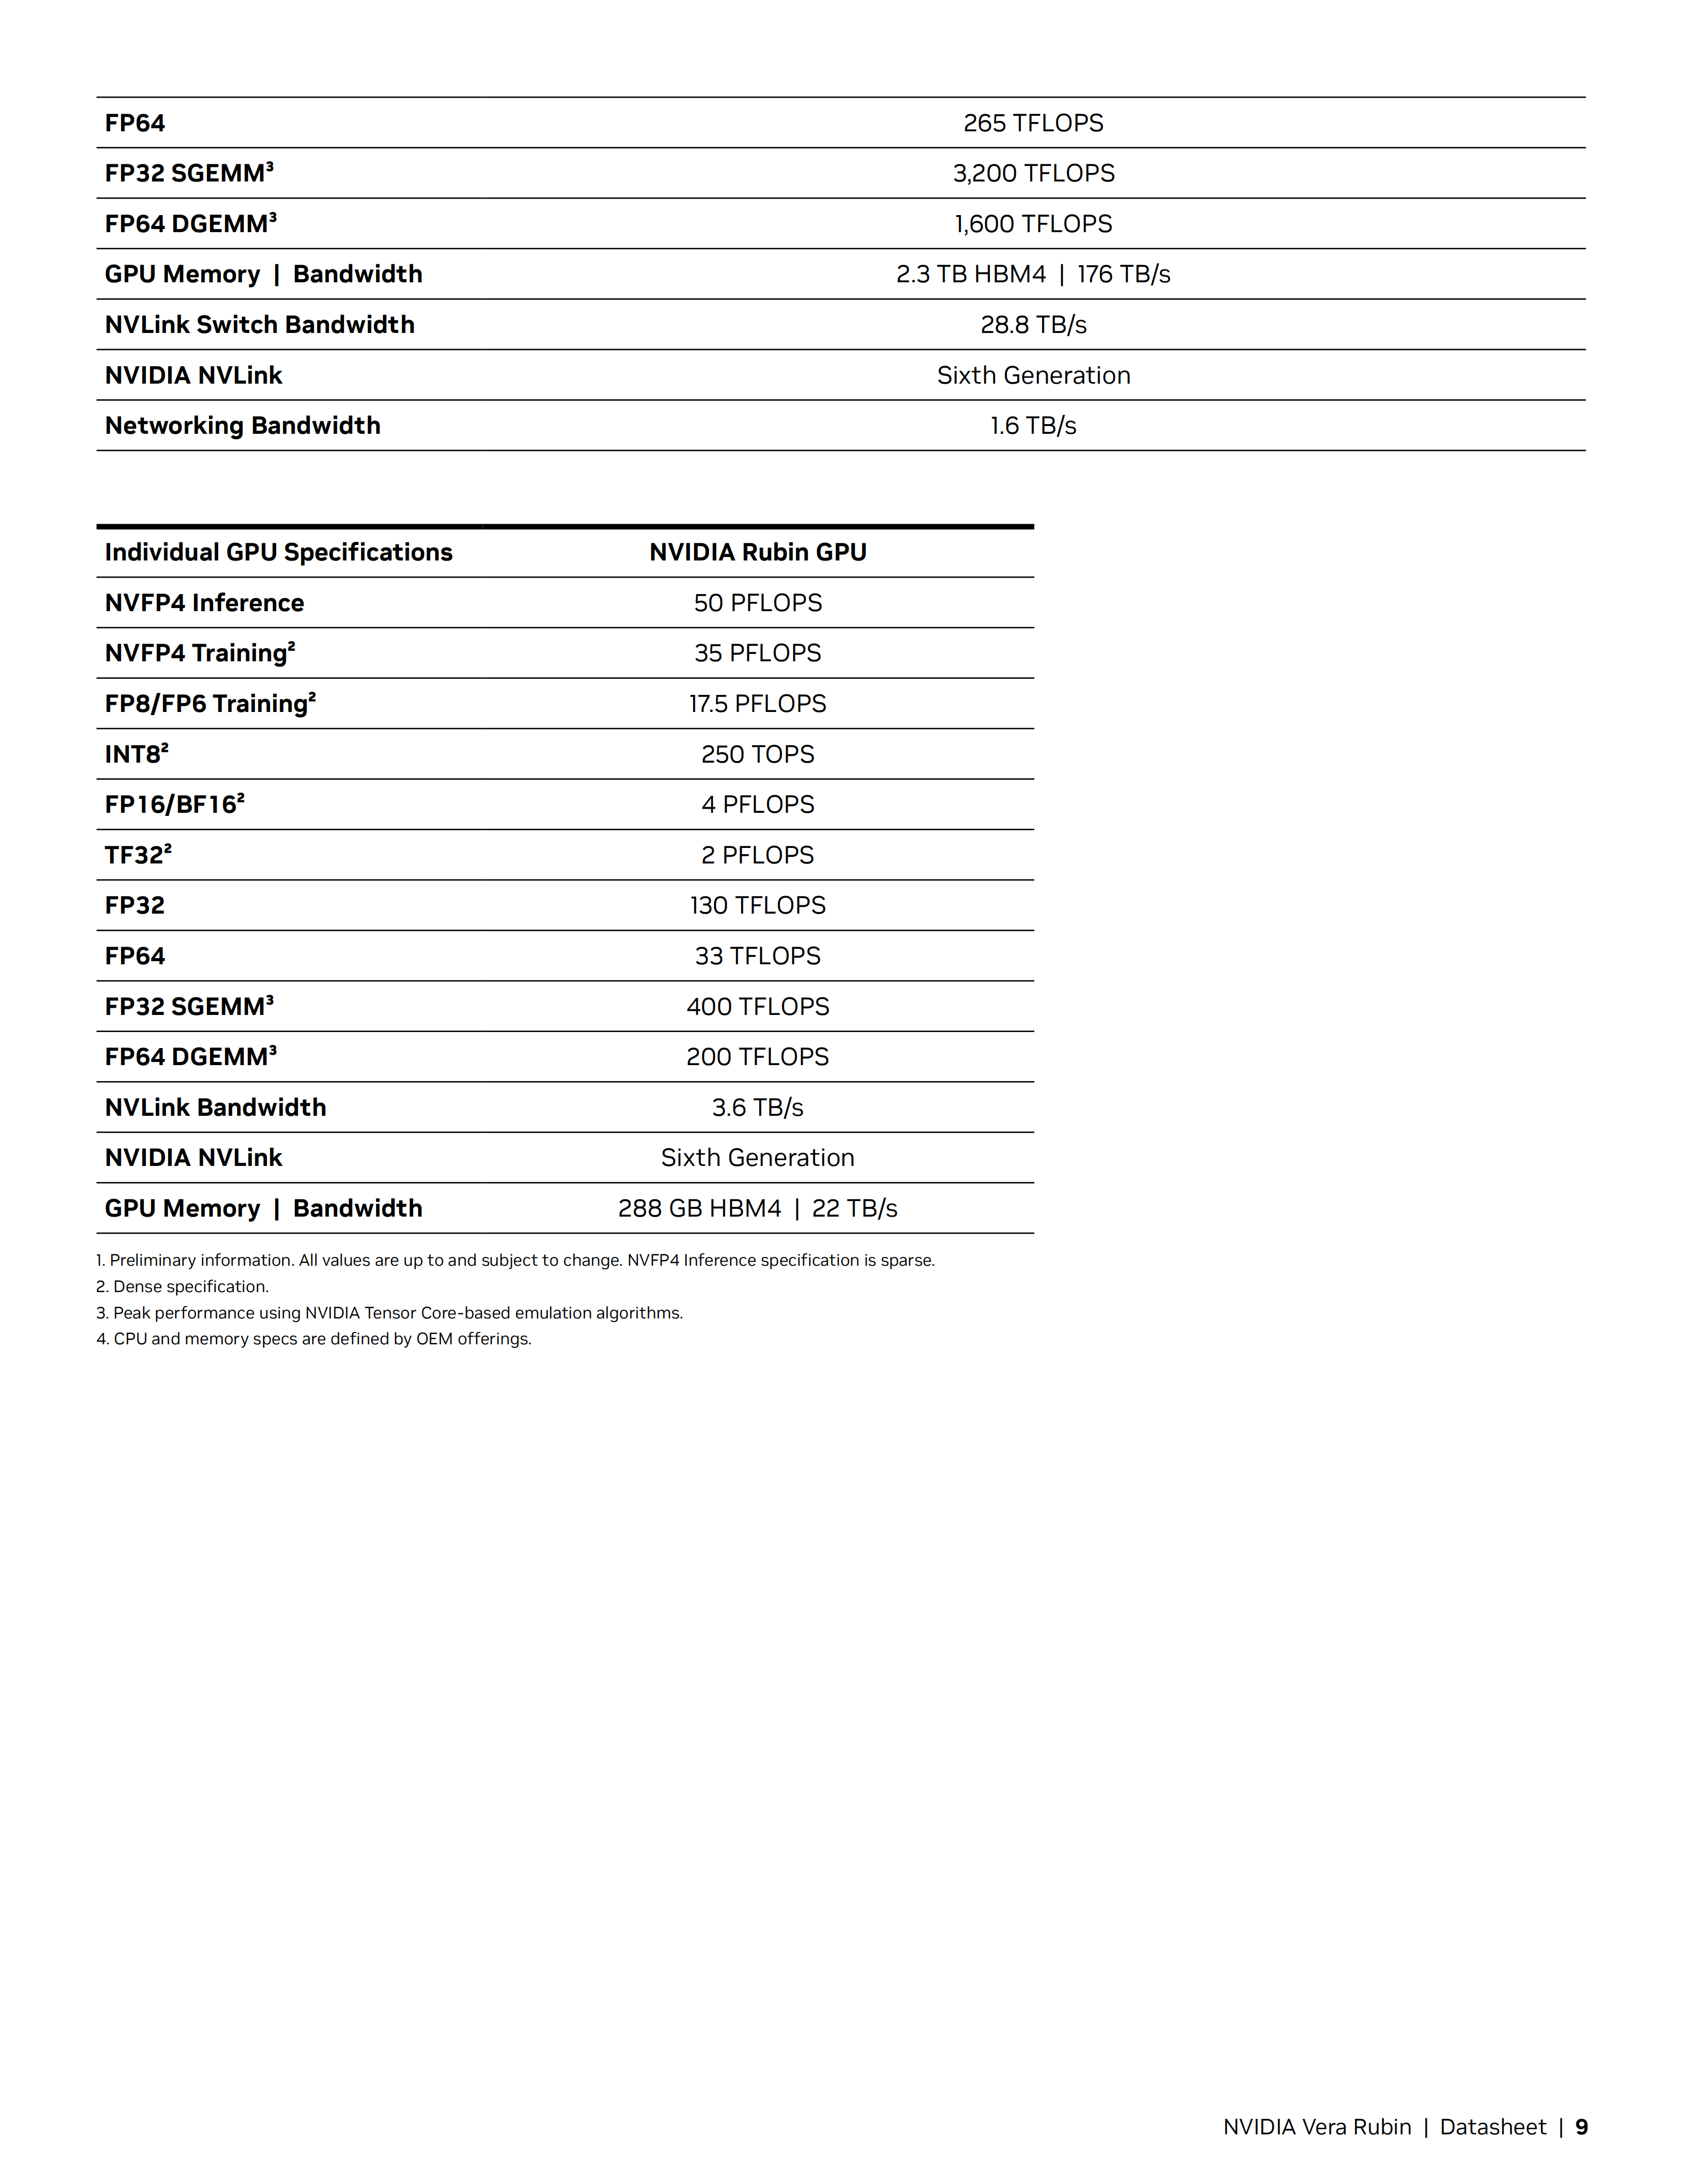
NVIDIA Vera Rubin is a full-stack, co-designed AI supercomputing platform purpose-built for the era of agentic AI. It is available in three configurations: NVL72 rack-scale systems, HGX NVL8 servers, and NVL4 scientific computing nodes, offering flexible deployment options for AI factories of different sizes.
The platform integrates Rubin GPUs, Vera CPUs, and sixth-generation NVLink interconnects, along with high-bandwidth HBM4 memory and a third-generation MGX liquid-cooled rack architecture.
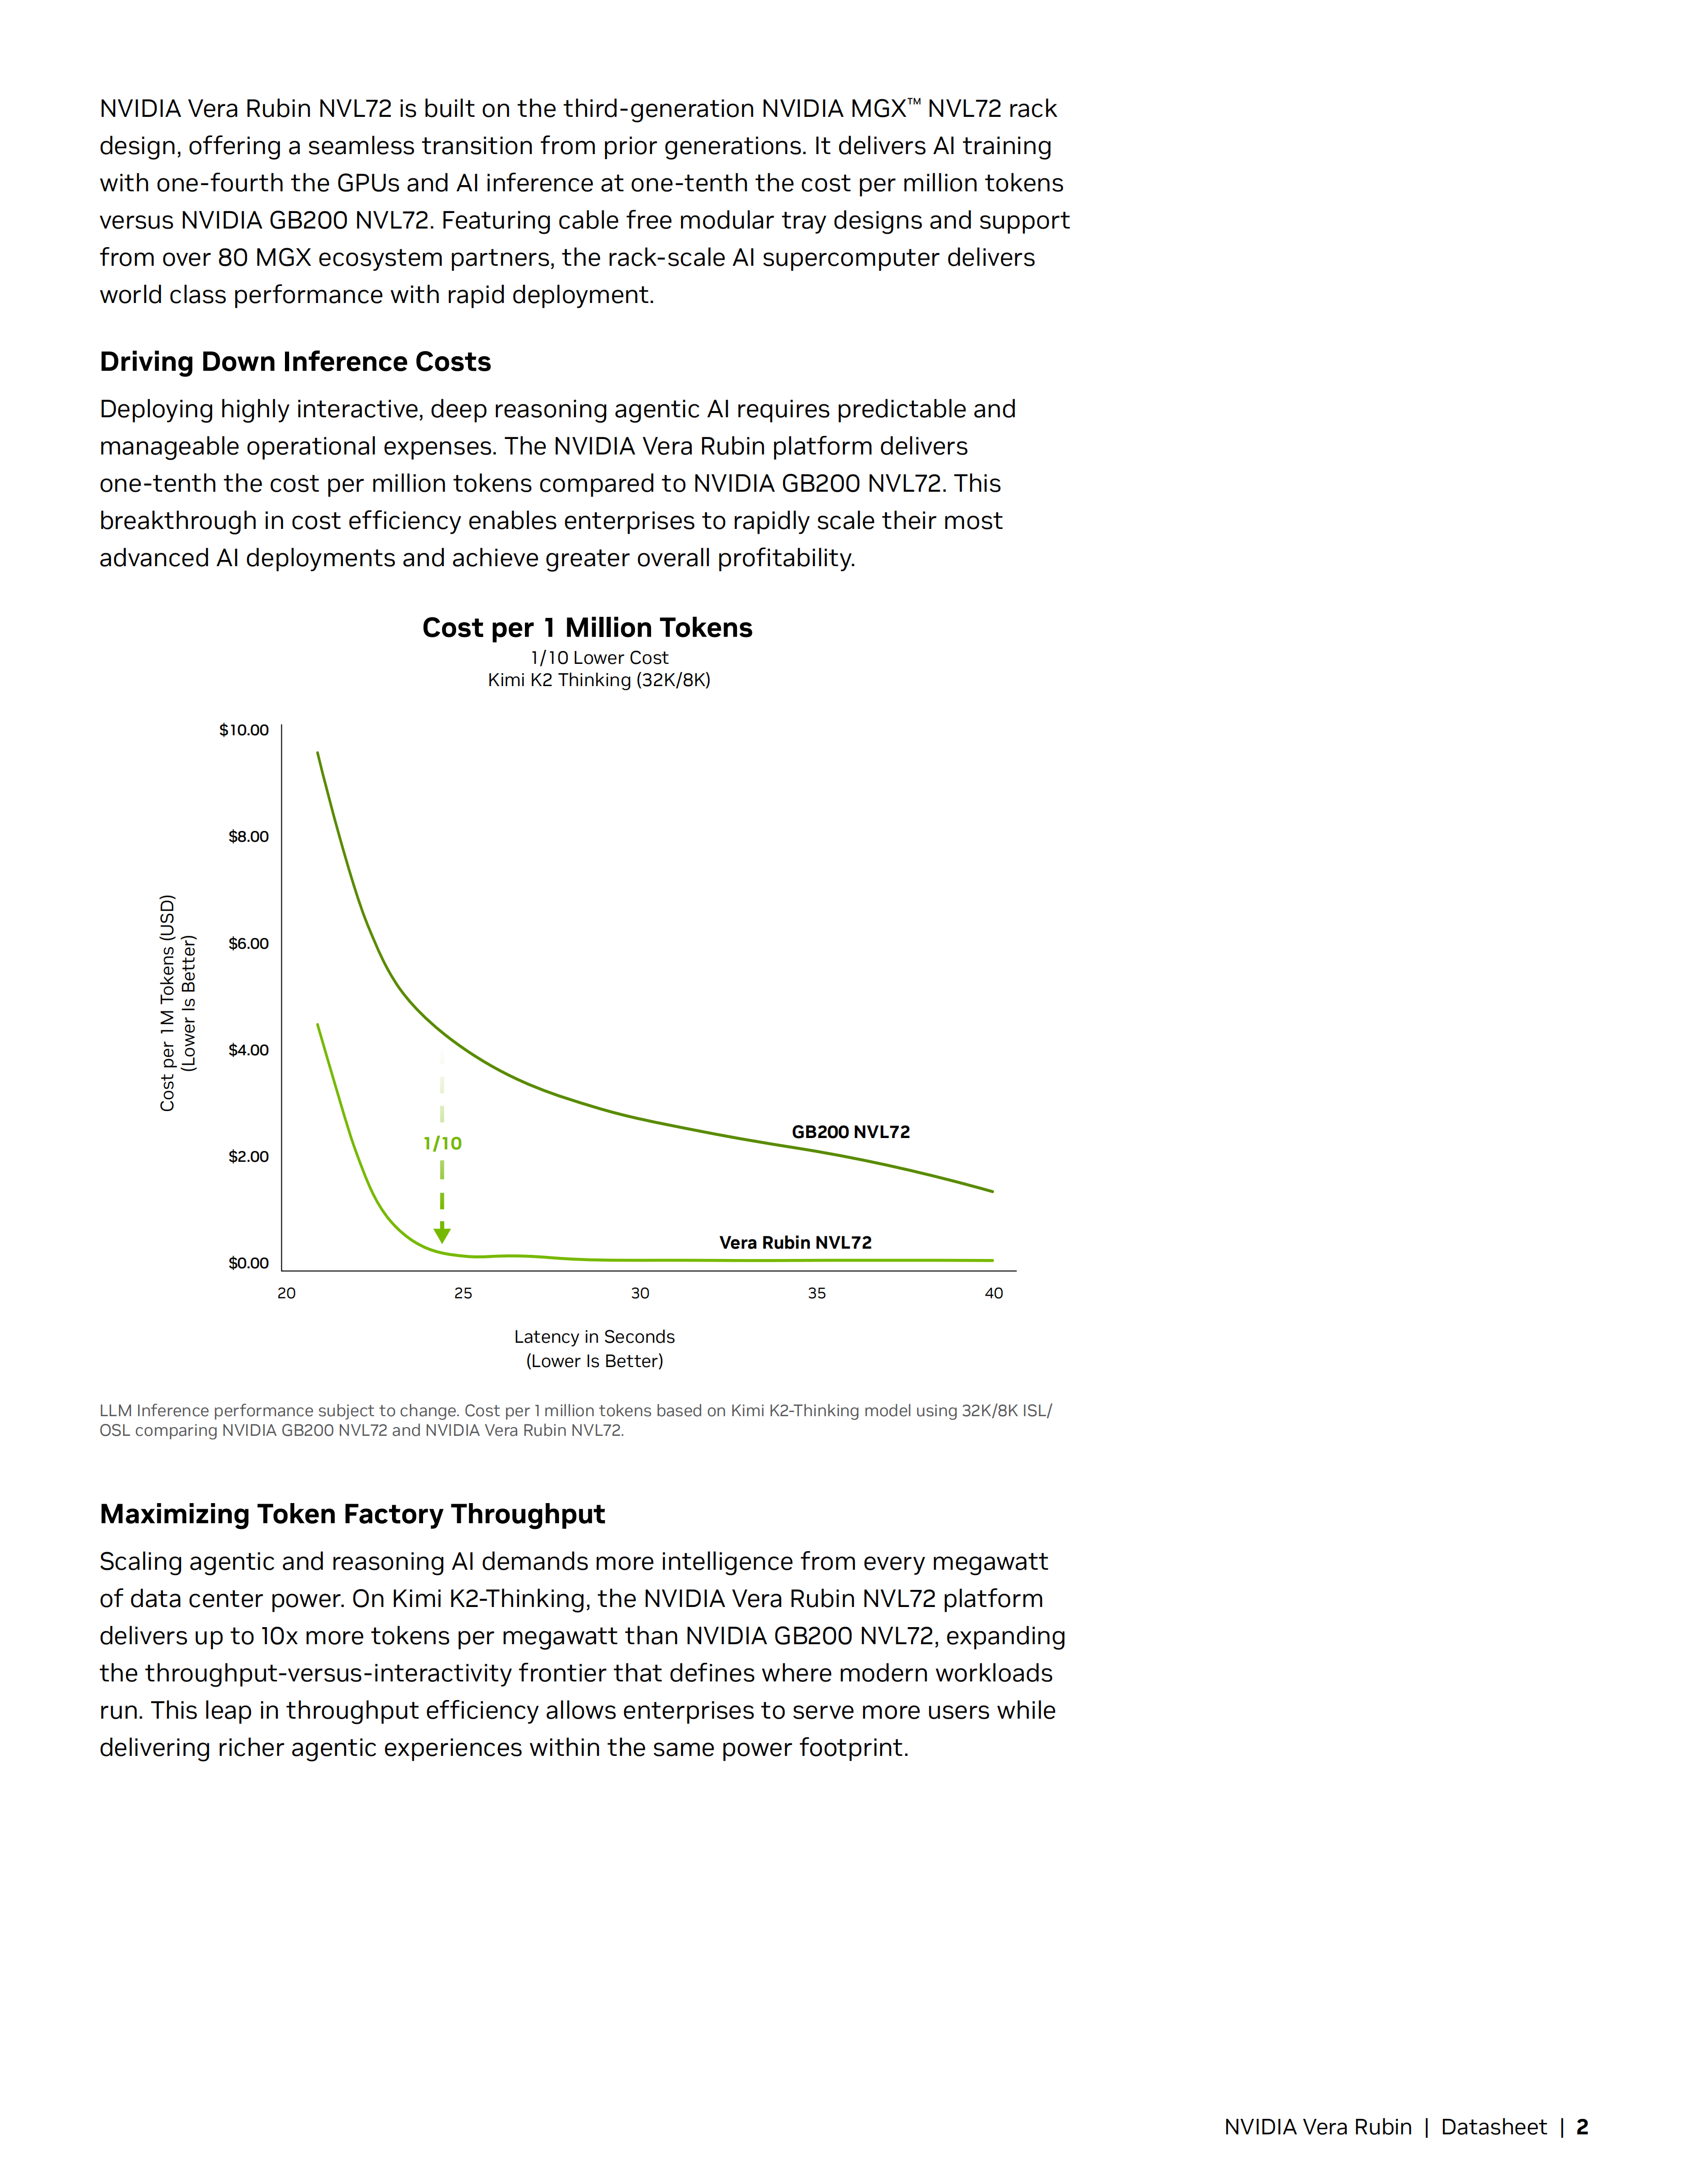
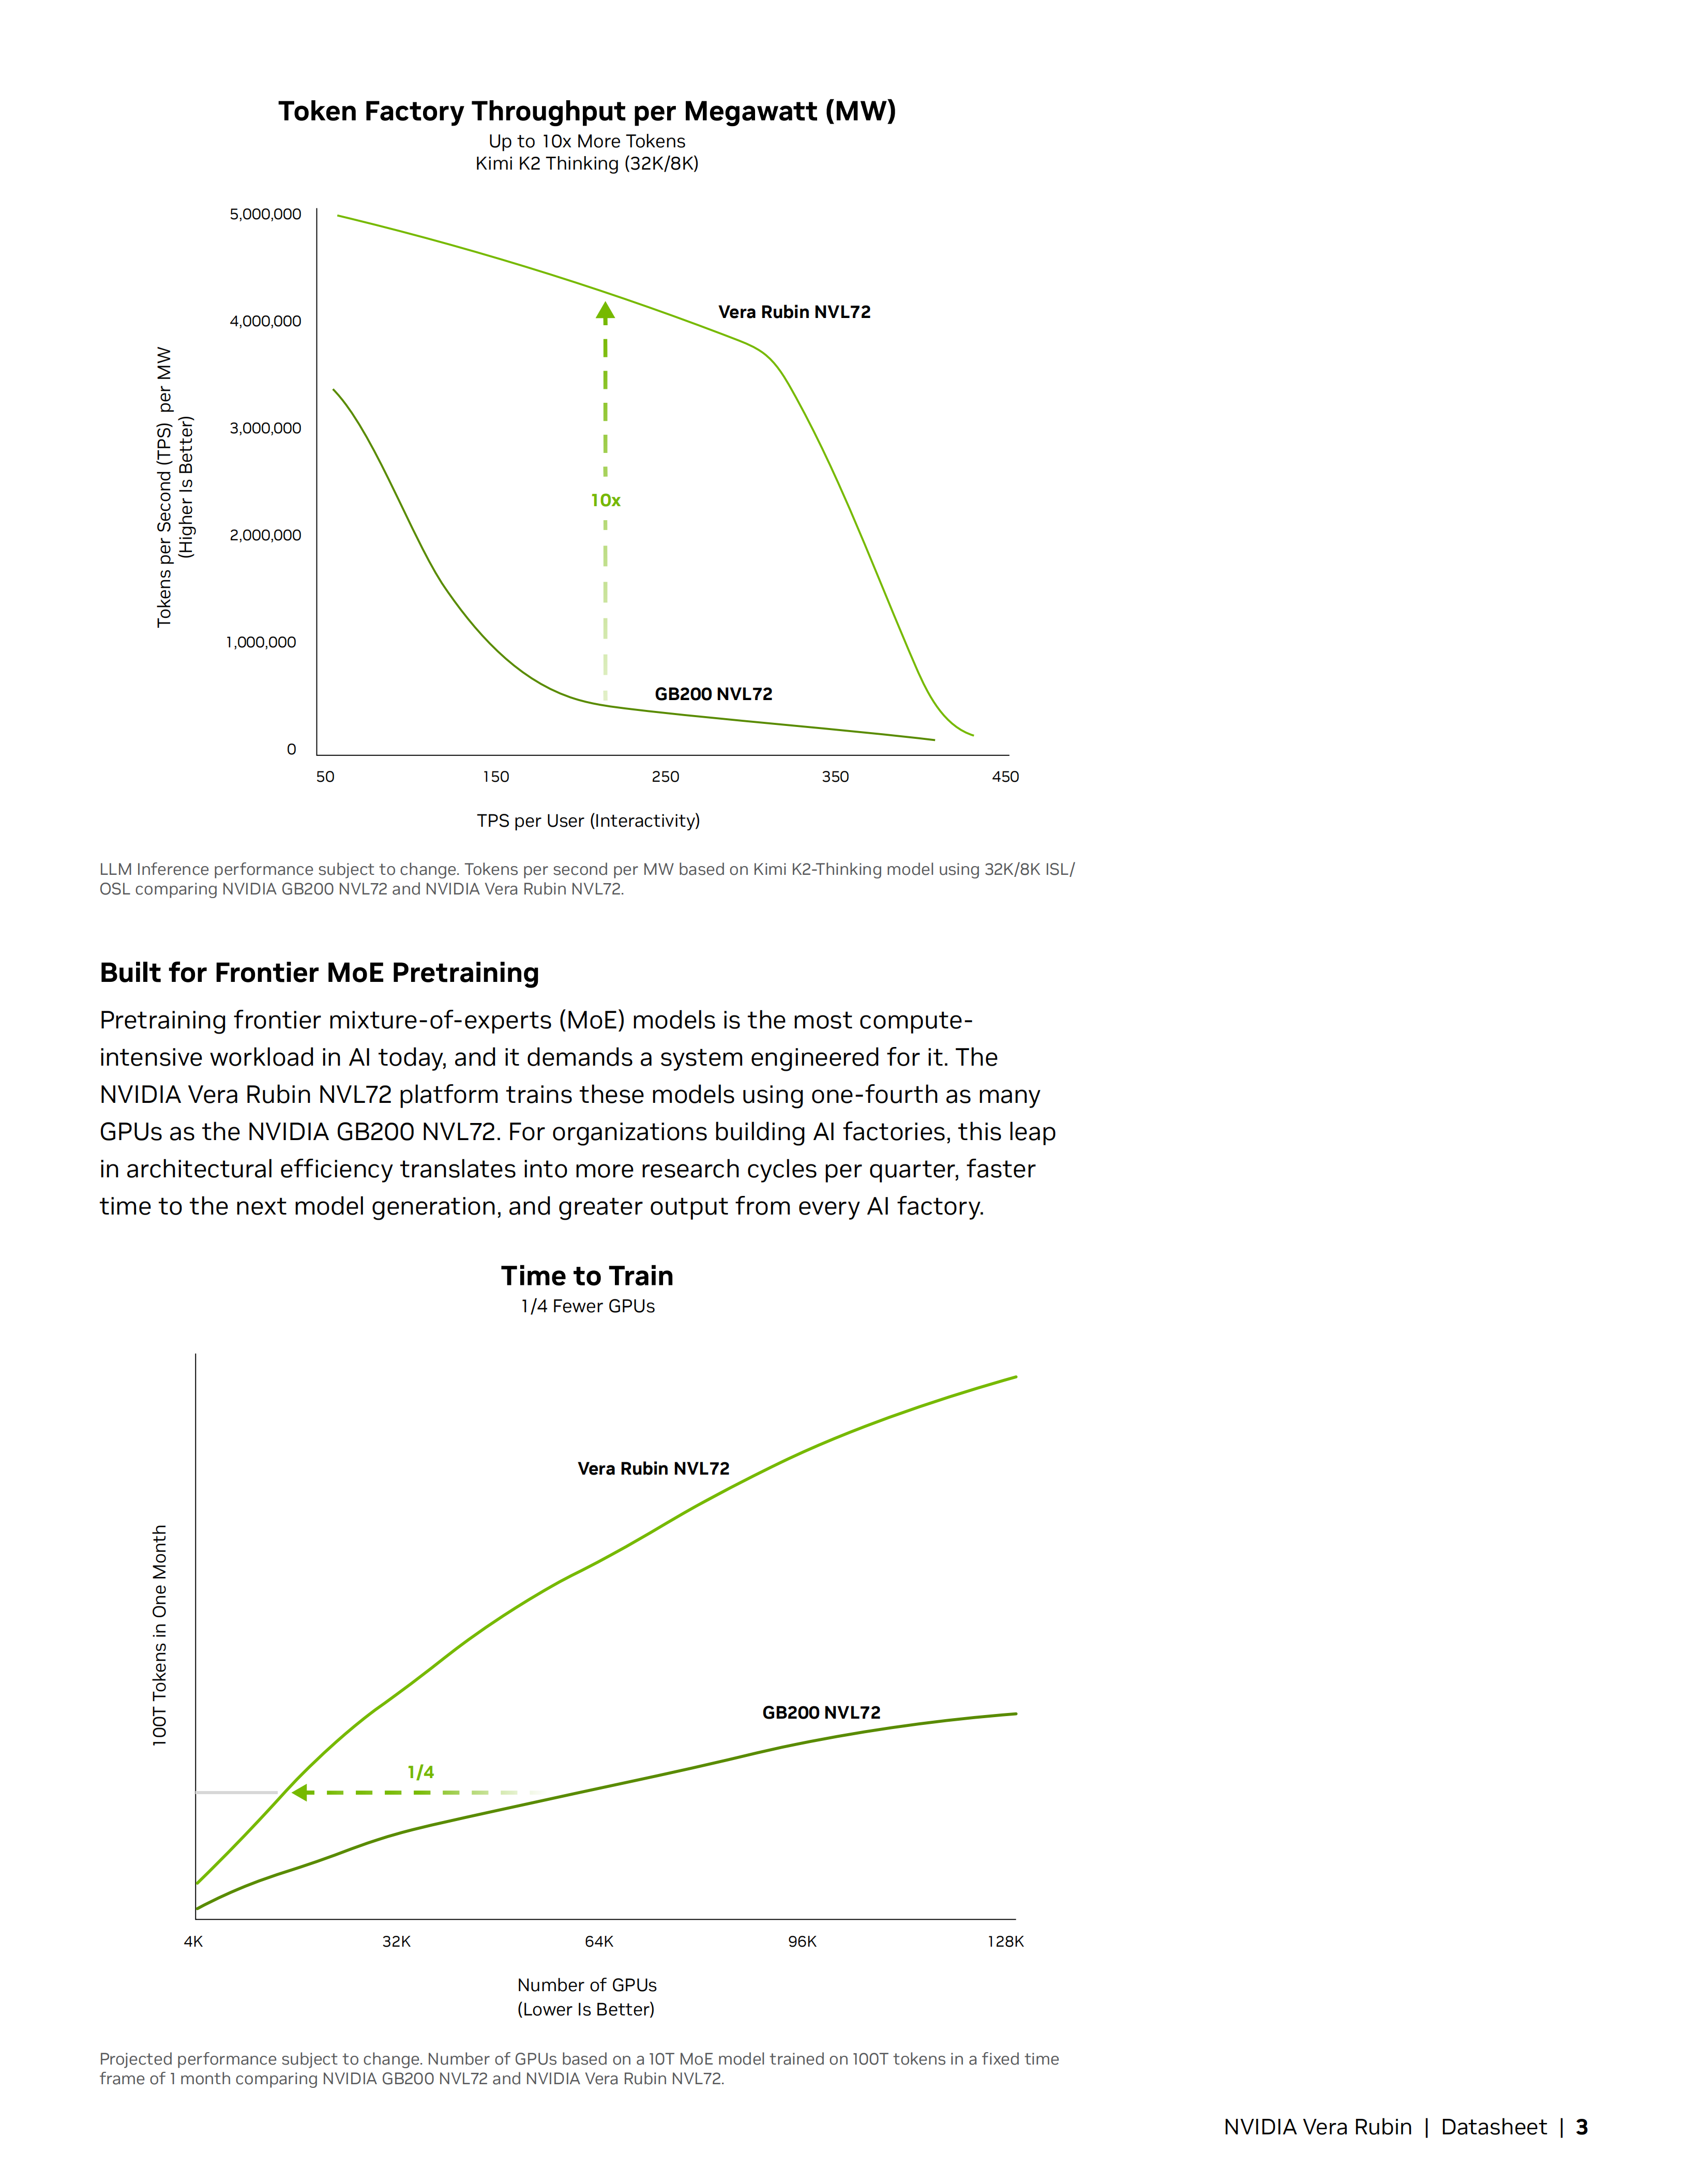
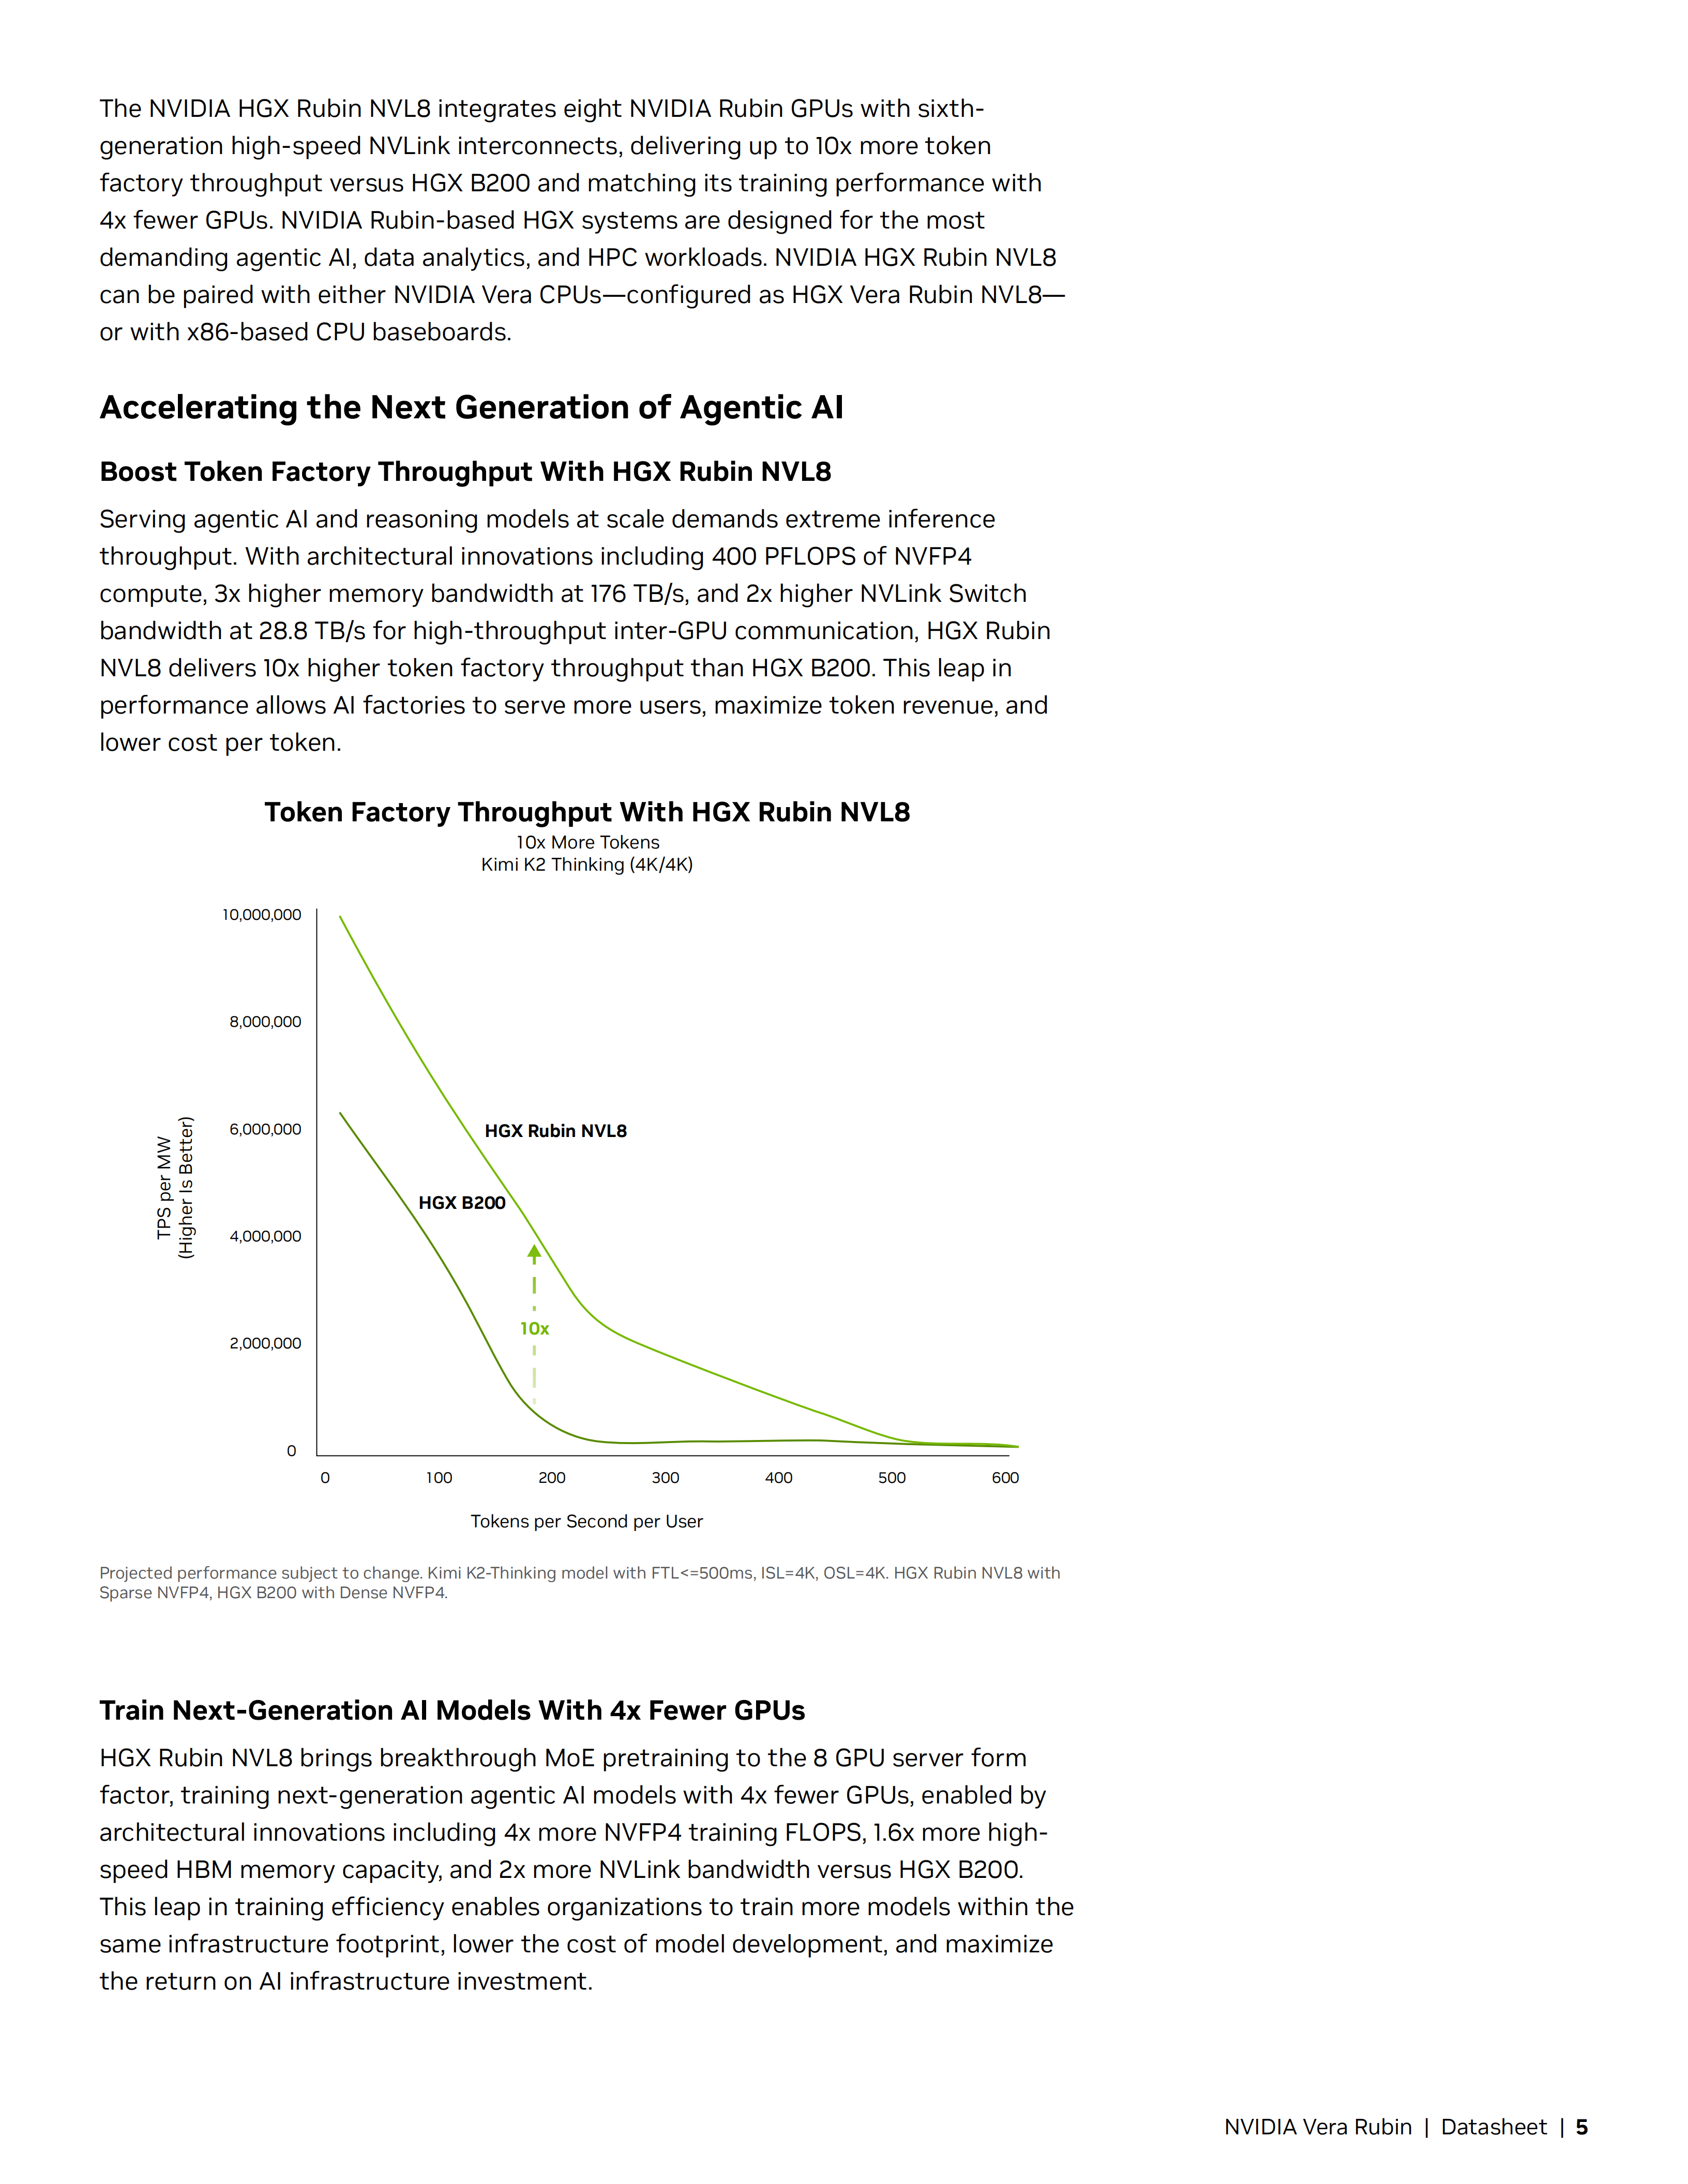
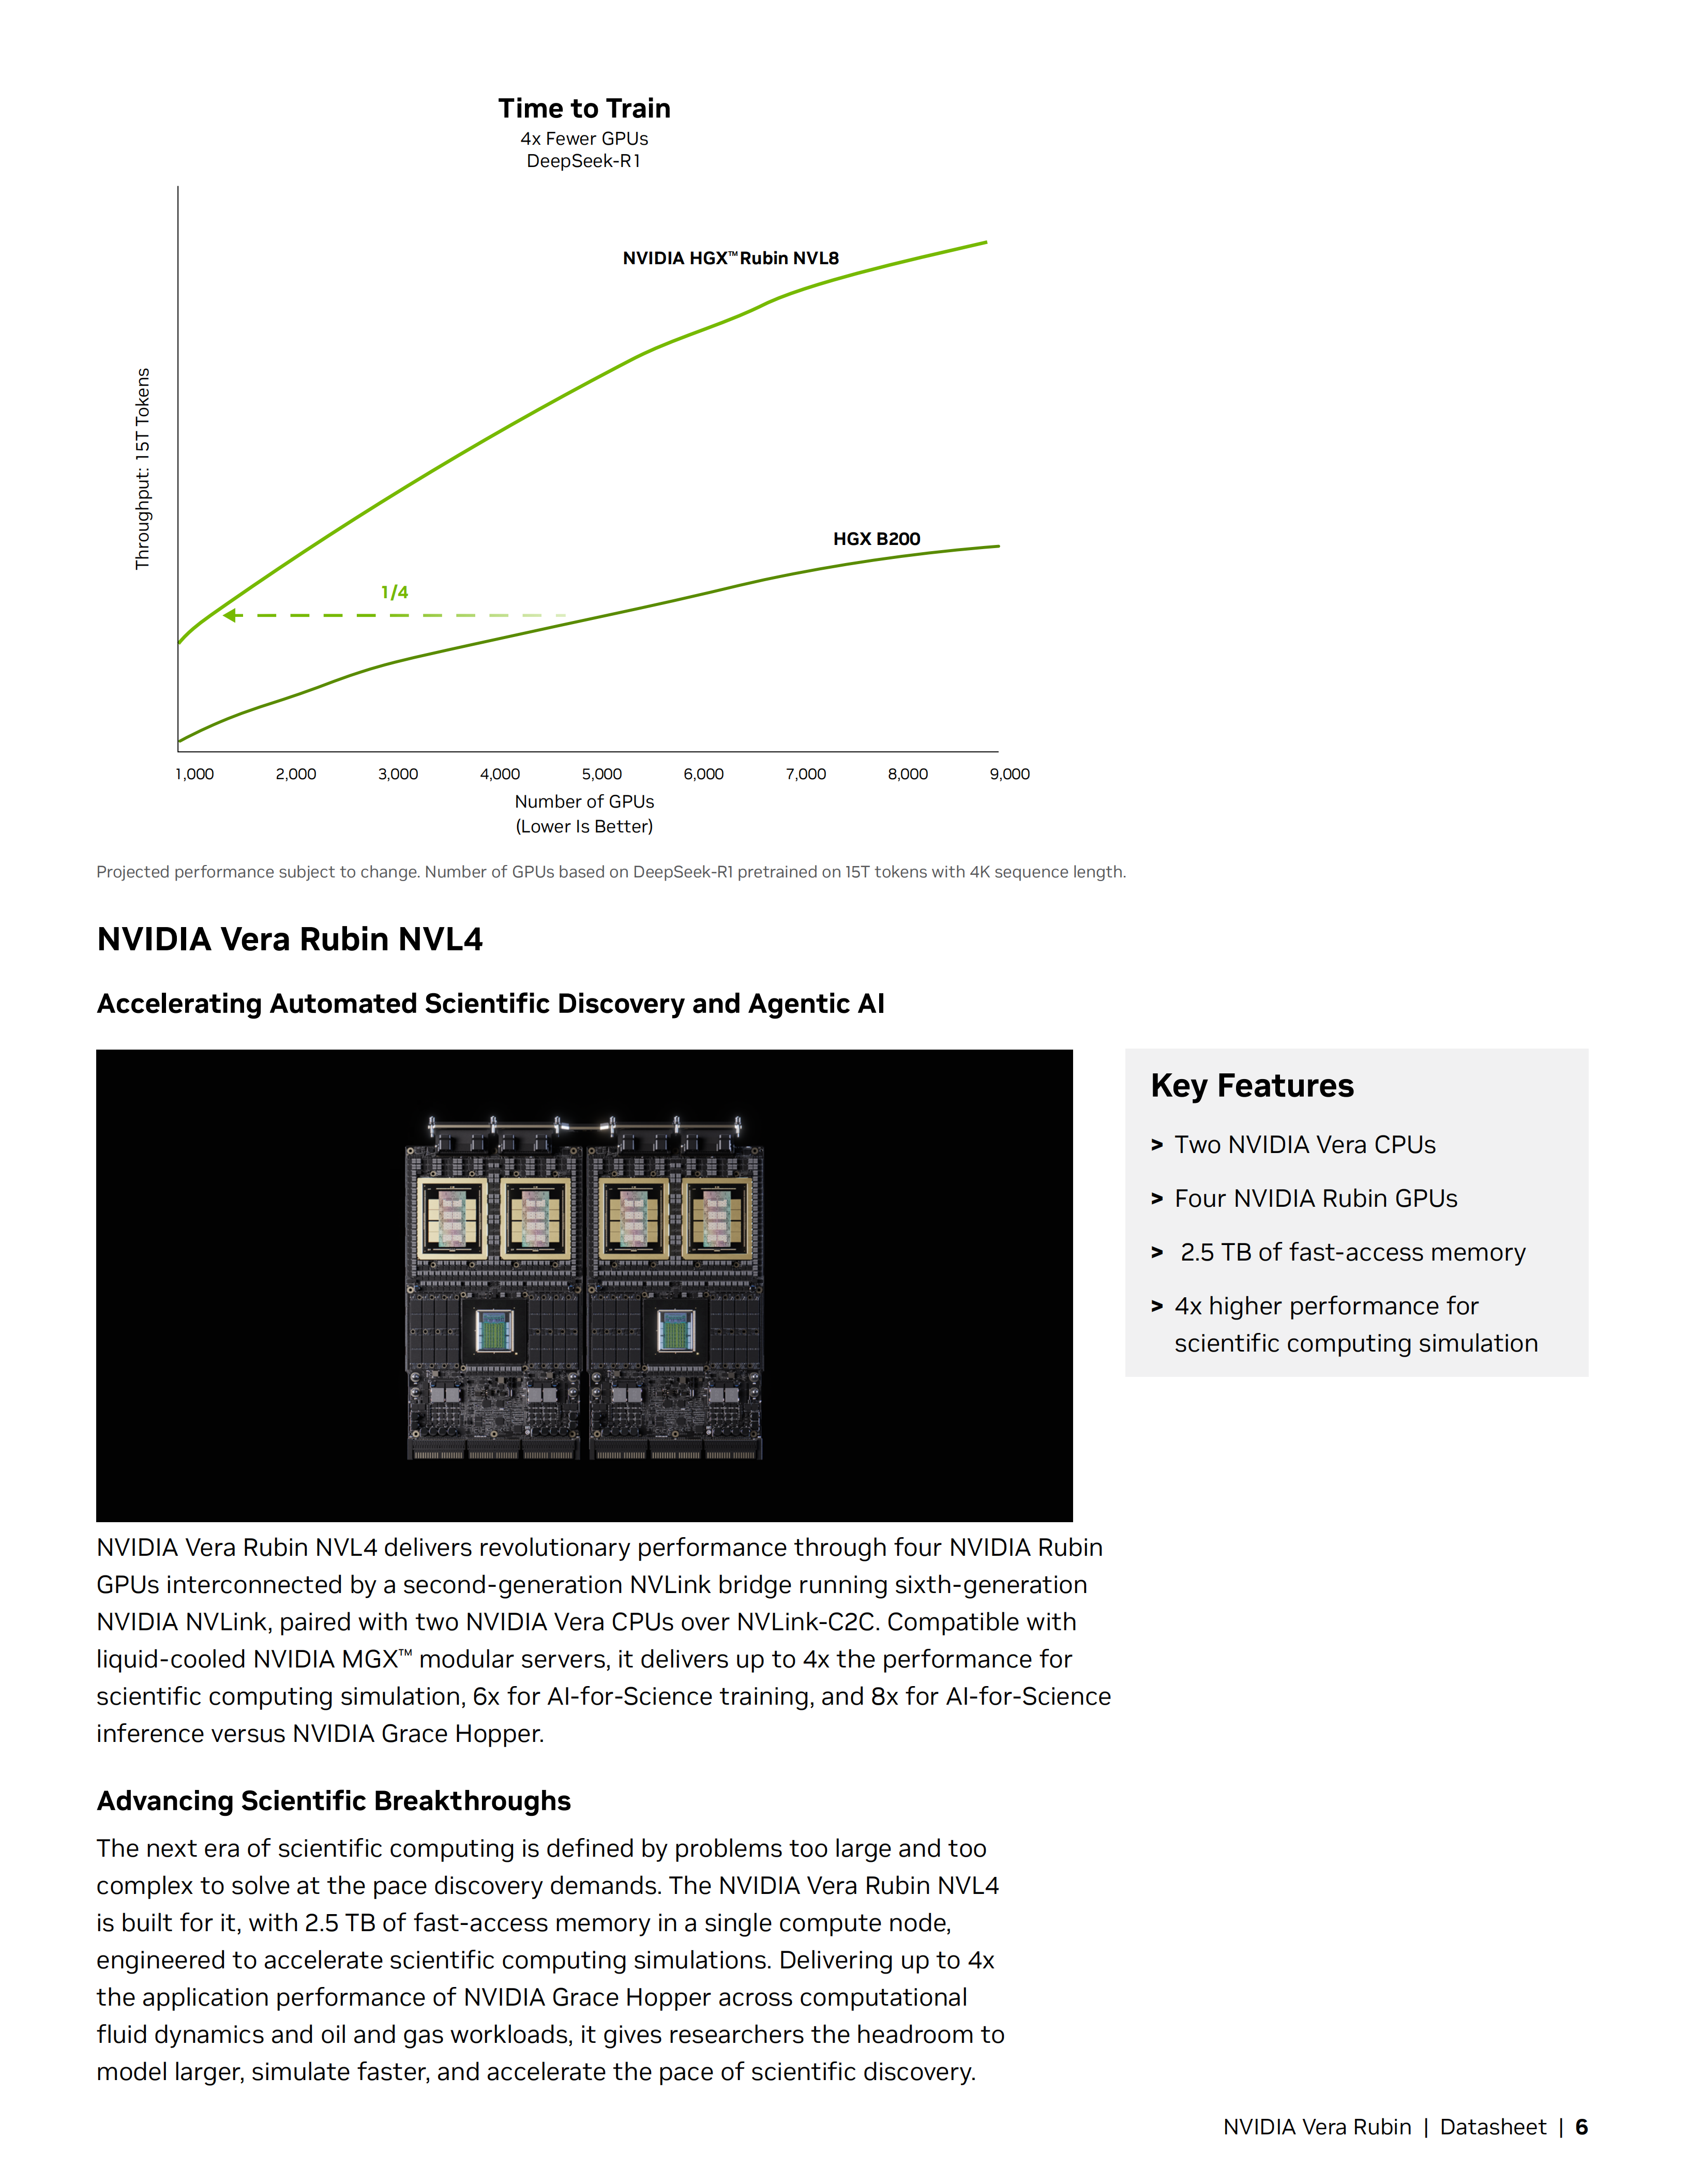
Compared to the GB200, Vera Rubin reduces inference costs per million tokens to one-tenth, delivers 10 times higher throughput per megawatt, and requires only one-quarter as many GPUs for training large Mixture-of-Experts (MoE) models. It also incorporates rack-scale confidential computing and a highly reliable RAS engine, providing a high-performance, energy-efficient, and cost-effective computing foundation for trillion-parameter model training, high-concurrency inference, and scientific computing.
Download Link: NVIDIA Vera Rubin Seven new chips, one incredible Al supercomputer